Data Product Distribution Framework
The 5 Distribution Models for Data Product Adoption in AI-Ready Enterprises

If we go straight to the heart of how Data Products differ from software or consumer products in their distribution logic, we'll tap into the innate nature of data and how it embeds itself into human processes and business undertakings.
A Data Product isn't sold or consumed: it's embedded into the living fabric of decisions and systems. In software, distribution is about channels, while in data, it's about propagation and how truth moves through an organisation without distortion.
The 5 Data Product Distribution Modes to Boost Data Adoption for Business
The data product distribution framework is the foundation for data adoption at scale, especially in enterprises where the core expertise isn't technology, data, or AI. Any product (not just data products) could be mediocre or great, but they get closest to user satisfaction when they reach the hands of he users, and hen users are enable to send critical feedback to the product development hub, enabling truly state of the art product experiences.

⚙️ Distribution Type 1: Internal Consumption / Data-as-a-Service
The value of a Data Product is in trustworthiness and usability. Internally, teams "sell" curated datasets, metrics, or models not for money, but for adoption. The currency is reliance and repeated usage: a dataset or model is only valuable when others integrate it into their work. Distribution begins with governed APIs, self-service catalogs with AI-driven smart search, and internal marketplaces that make truth discoverable, reliable, and scalable across the organisation.
🏪 Distribution Type 2: Integration in Embedded Workflows
Data only delivers value when it meets decision-making contexts. Placement of data product outcomes in pre-existing channels of decisions ensures Data Products are encountered where work happens. Whether embedded in CRMs, dashboards, operational systems, or AI copilots, insights are integrated into workflows rather than discovered separately. This reduces procedural friction, turns data into actionable directions (strategy), and transforms data artefacts like tables and queries into experiences.
🧩 Distribution Type 3: Shared Data Product Models
For mature organisations, distribution extends beyond internal teams. Co-operating data products mean sharing models or curated datasets with partners, regulators, or industry collaborators. This expands the reach of insights and creates new value streams, but requires high governance, accountability, and clear contracts. Distribution here is about trust across organisational boundaries.
⏱️ Distribution Type 4: Controlled Democratisation
Democratisation without control is confusion and an overwhelming experience of options for data consumers. Sharing aspects of the data product model provides scoped and temporary access for experiments, analytics, or AI/ML training. This allows teams to explore and innovate while maintaining privacy, security, and compliance. Controlled access transforms data from a bottleneck into an enabler, supporting safe experiments (a must-have for data and AI applications) at scale.
🧭 Distribution Type 5: Referrals for Cross-Team Virality
Once a Data Product proves its value, adoption increases through the network effect. The Referral channel in data is a byproduct and proof of the data product's impact. In fact, even a by product of an already existing data distribution model that works. When one team leverages a model to solve a real problem, others follow. Storytelling, reproducibility, and internal case studies act as the engine that propagates trust and accelerates uptake. In essence, virality in data is socialised confidence in truth.
When extended to Data Applications and AI Applications, distribution evolves from truth (data-as-a-service) to understanding (data applications) to judgment (AI applications).
- Internal "selling" or the more appropriate term "advocating" (type 1) establishes trust,
- embedding outcomes (type 2) creates experience,
- shared models (type 3) expands influence and preserves integrity with increased validation points,
- governance as a distribution model (type 4) targets the right touchpoints, and
- referral (type 5) spreads adoption further.
If Your Data Products Aren't Distributed, They're Invisible.
Distribution is designing an ecosystem where truth flows naturally to the decisions that depend on it.
Connect with a community data expert
A no-cost session with a practitioner who's been where you are.
About Modern Data 101
Modern Data 101 is a movement redefining how the world thinks about data. A community built by the same team behind the world’s first data operating system, Modern Data 101 sits at the intersection of data, product thinking, and AI. Spread across 150+ countries, the community brings together a global network of practitioners, architects, and leaders who are actively building the next generation of data systems.
At its core, Modern Data 101 exists to simplify the journey from raw data to tangible and observable impact. It advocates high-potential data systems and next-gen architectures to unify and activate insights and automation across analytics, applications, and operational workflows at the edge.
In a world shifting from data stacks to AI ecosystems, Modern Data 101 helps teams not just navigate the change but lead it.


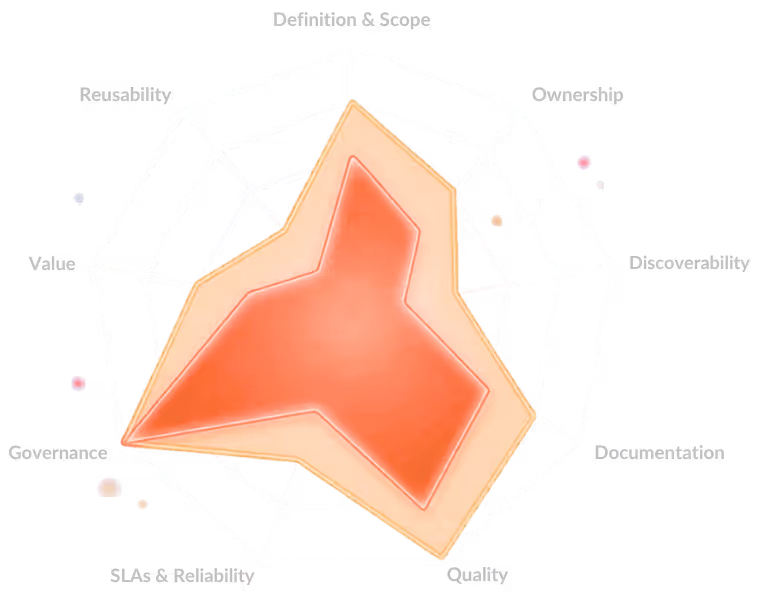
A 9-dimension self-assessment used by 100+ data teams to benchmark strategy, ownership, and platform readiness.

Animesh Kumar
Animesh Kumar is the Co-Founder and Chief Technology Officer at The Modern Data Company, where he leads the design and development of DataOS, the company’s flagship data operating system. With over two decades in data engineering and platform development, he is also the founding curator of Modern Data 101, an independent community for data leaders and practitioners, and a contributor to the Data Developer Platform (DDP) specification, shaping how the industry approaches data products and platforms.
Read the ideas here. Build them with The Modern Data Company.
Modern Data 101 is where the data community thinks out loud. When you're ready to move from articles to architecture, data products, governed AI pipelines, or a full Data Operating System; the team behind this community can help you build it.
Continue reading