

When AI Agents Become Data Consumers
As AI agents move from generating answers to taking autonomous actions, this interview examines how enterprise architecture, governance, semantic layers, and BI must evolve to deliver deterministic, secure, and trustworthy outcomes.
Power Questions
Min Read
Domains Covered
Published
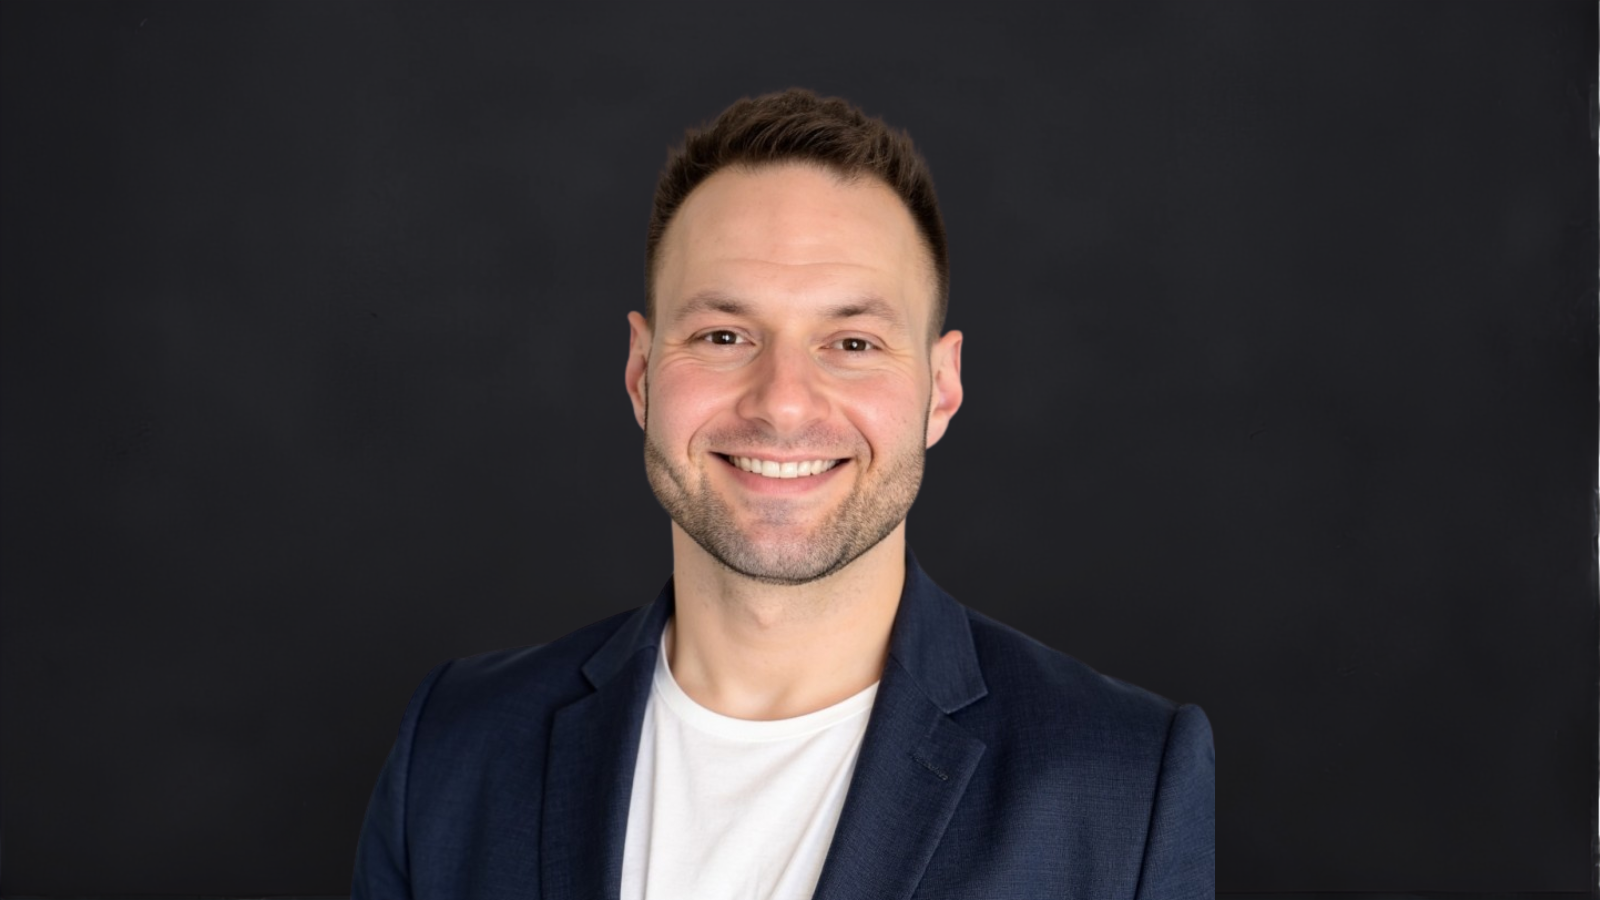
Dan Merzlyak is a senior data, analytics, and AI executive with extensive experience leading global teams and building data-driven capabilities across financial services, technology, and private equity-backed businesses. His expertise spans data strategy, analytics, AI, business intelligence, and technology operations, with a strong focus on turning enterprise data into actionable insights and measurable business value.
Dan currently serves as Senior Vice President, Global Head of Data, Analytics, and AI at EDB, where he leads the global Data, Analytics, and AI team while also overseeing IT infrastructure, system integrations, and internal and customer-facing applications. Previously, he was a Director at BlackRock, leading the Aladdin Data Migration and Business Intelligence Practice, and has held leadership and consulting roles at the London Stock Exchange Group, Cerberus Capital Management, PwC, and EY.
Beyond his executive role, Dan is a Global Editorial Board Member at CDO Magazine, a member of the AIM Leaders Council, and a Governing Body Member of the New York CDAO Community. His industry recognition includes CDO Magazine’s 40 Under 40, OnConferences’ Top 100 Data & Analytics Leaders, and AIM’s AI Innovator of the Year. We’re thrilled to feature his insights on Modern Data 101.
This interview explores the architectural shift required as AI agents become active consumers of enterprise data from governed context and agent-level access controls to natural-language analytics, semantic layers, observability, and deterministic business logic. It also examines why traditional BI environments must be modernized before organizations can trust agents to make or influence business decisions.
What architectural capabilities become essential when applications move from generative AI responses to autonomous agentic workflows?
The shift is from a model producing text a human reads to a system taking actions a human may never see. That changes the bar on almost everything underneath it.
- The first thing that becomes non-negotiable is determinism where it matters. A generative response can be a little different every time and nobody is harmed. An agent that calculates ARR, answers a support ticket, or updates a record cannot. So the logic that produces those outcomes has to move out of the prompt and into the data and AI platform, defined once, tested, and versioned like any other production asset. For structured data that means the metric is computed in the data layer and the model reasons over the result. For unstructured data and multi-step reasoning, it means the retrieval, the tool calls, the guardrails, and the decision points live in the application stack as governed workflow components, not as instructions the model is trusted to follow on the fly. Either way, the model interprets and orchestrates; it does not become the place where the answer is defined.
- Second is identity and scope. Agents need their own credentials, their own permissions, and their own audit trail. If an agent runs under a shared service account with broad access, you have no way to answer "who did this and why" when something goes wrong. We treat agents as principals in the same governance model as people.
- Third is observability at the reasoning level, not just the infrastructure level. Logs and uptime are table stakes. What you actually need is a trace of every tool call, every query, every intermediate step, so you can replay a decision and see where it went sideways.
- Fourth is orchestration with intent routing. Internally we run Mission Control AI, a LangGraph-orchestrated agent that classifies what a user is actually asking, routes it to the right specialized agent or tool, applies the access rules for that person, and carries the result back through one interface. That routing layer is where policy gets enforced and where you get a single view of what agents are doing and what they cost. Without it you end up with dozens of point solutions and no control plane.
And underneath all of it, sovereignty. For the workloads that matter most, the data cannot leave your boundary and the models have to run where you say they run. We built our internal agent platform on EDB Postgres AI for exactly that reason.
How should enterprise data architecture provide agents with the context they need without giving them unrestricted access to everything?
The wrong instinct is to give the agent everything and compensate with instructions. More table descriptions, more metadata, more prompt text telling it which version to trust. That does not remove ambiguity, it moves it into the reasoning layer. The agent reads more, thinks longer, spends more tokens, and still is not deterministic.
The right approach is to shrink the surface the agent sees and make what it sees unambiguous. Three things.
Curate the consumption layer. Shared fact and dimension tables at a declared level of detail, aggregates above them where each measure is calculated exactly once, and a semantic layer on top that handles joins, naming, and access rules but holds no business logic. When a metric lives in one place, the agent cannot pick the wrong one.
Enforce access in the data, not in the agent. Row-level and column-level security, role and attribute-based controls, applied at the database and semantic layer so the same question from two different people returns two appropriately scoped answers. The agent does not decide what it is allowed to see. The platform does. Internally, access is role-gated at the routing layer regardless of who is asking, so the same interface serves a finance leader and a new sales rep without any prompt gymnastics.
Make the catalog the source of truth for what exists. We run a metadata catalog across the estate with lineage and ownership on every asset, and we register agents in it alongside tables and dashboards. When an agent needs context, it gets governed metadata from the catalog, not a description someone pasted into a system prompt eighteen months ago.
The principle is simple: context should be a build-time property of the platform that you can test, not a runtime property of the prompt that you can only observe.
Does natural-language analytics eventually replace dashboards, or does it change what dashboards are for?
It changes what they are for, and in doing so it retires a lot of them.
Most dashboards exist because someone asked a question once and an analyst built a permanent answer. Then the question changed and the dashboard did not. Natural-language analytics eats that whole category. If a leader can ask "how did renewals in EMEA trend against forecast this quarter" and get a governed, correct answer in seconds, the dashboard that approximated that question has no reason to exist.
What survives is the dashboard as a deterministic, scheduled output. The board pack. The weekly operating review. The number that has to be identical every Monday morning for every person who looks at it. Those are not exploratory; they are contracts. Dashboards are very good at contracts.
The mistake is running the two as separate systems. If your dashboards read from one set of tables and your agents read from another, you will eventually have two numbers, and the argument about which one is right will cost you more than either system did. We made the call internally to rebuild reporting on the same semantic layer our agents use. Same governed definitions, same natural-language interface, with dashboards as the scheduled output of that platform rather than a parallel estate. Where a BI tool could not sit on that layer, we stopped trying to save it.
If you want a signal of where the market is heading, look at how many data teams are re-evaluating their BI contracts this year and ask why.
What needs to be modernized in traditional BI environments before natural-language analytics can be trusted for business decisions?
Three things, in order.
- Kill the duplication. Most mature BI estates have the same metric defined in several tables, each shaped for a specific report and each calculated slightly differently. A human analyst knew which one to trust. An agent does not. It picks one and answers with full confidence. Duplication used to be a cost. Now it is a correctness problem.
- Pull business logic out of the BI tool and out of report-specific tables and into a single governed layer. Metric definitions become an owned asset with a name, an owner, tests, and lineage, not something every project rebuilds.
- Then instrument for trust. Every natural-language answer should be traceable back to the query it ran, the tables it touched, and the definition it used. If a leader cannot click through from a number to its lineage, they will not bet on it, and they should not.
Only after those three does it make sense to put a language interface in front of the data. Doing it earlier just gives you a faster way to get the wrong answer.
As agents become consumers of analytics, how should semantic layers evolve?
The semantic layer has to stop being a BI convenience and become a governance boundary.
Historically it was a thin translation layer for one tool: friendly names, some joins, maybe a few calculated fields. Going forward it needs to be tool-agnostic and consumed by dashboards, agents, notebooks, and downstream applications alike. It should own joins, naming, and access rules. It should not own business logic; that belongs in the data, deterministic and tested, one level down.
It also needs to speak the language agents speak. That means a machine-readable contract: what measures exist, what grain they are valid at, what dimensions they can be sliced by, who is allowed to see them. When an agent asks a question, the semantic layer should be able to say yes, no, or "not at that level of detail" without the model having to guess.
And it needs to be versioned and observable like code. When a metric definition changes, every consumer should see the change at the same moment, and you should be able to see who consumed the old version and when. Once agents are running unattended on top of it, the semantic layer is production infrastructure. It should be treated that way.
More Visionary Spotlights
Want to be featured in a Visionary Spotlight?
We interview C-suite leaders shaping the future of data, AI and analytics. If that's you, or someone you know, get in touch.